Build your own FDE salary table from public Greenhouse data in about 40 lines of Python
In US states with pay transparency laws, FDE pay ranges often appear in the job posting itself. Pass the right parameters and remember to divide by 100, and you can build a salary table of your own.
In brief
- The Greenhouse Job Board GET endpoints need no API key, but you only get pay ranges if you pass pay_transparency=true
- Amounts sit in min_cents and max_cents, so 5000000 means 50,000.00 USD
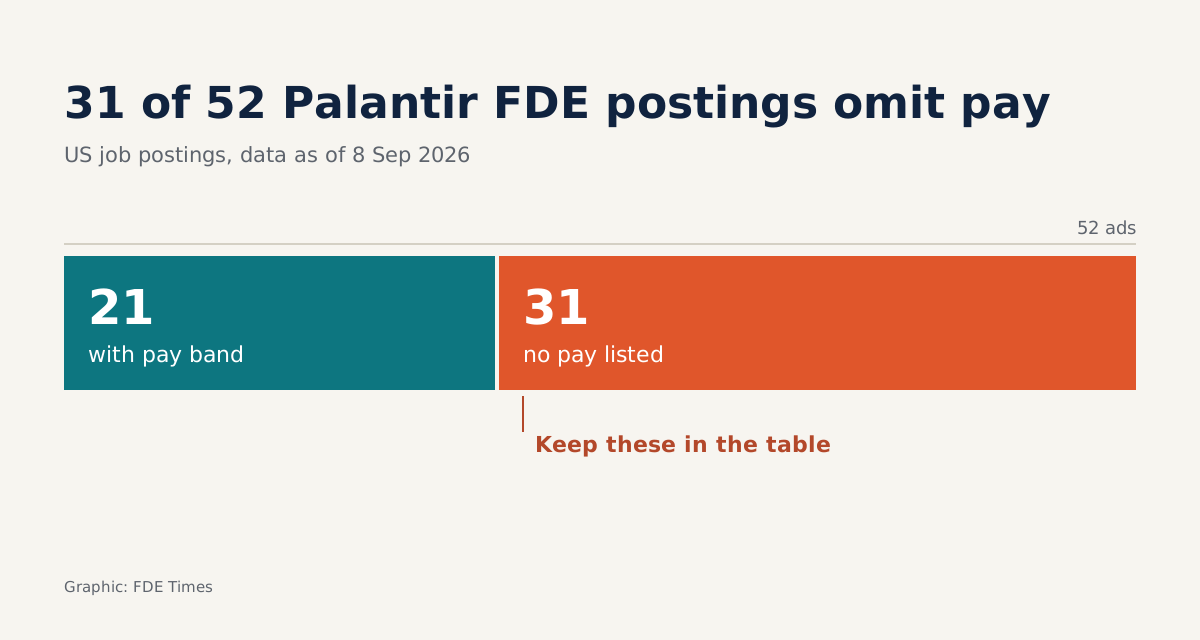
- Postings without a pay range are common: Palantir lists one on only 21 of 52 US postings
One number in the Greenhouse documentation can throw off a whole salary table: "min_cents":5000000. Forget that it is in cents and you will think a role pays 5 million USD, when the real figure is 50,000.00 USD.
This guide shows how to avoid small traps like that one. You will write a short Python script that calls Greenhouse’s public jobs API, filters for Forward Deployed Engineer postings, converts the pay ranges into readable units and writes the result to a CSV file.
The result is an FDE salary table you built yourself, with its source and the date the data was pulled, instead of a figure passed around by word of mouth.
The table is useful if you are preparing to negotiate an offer. The bigger payoff is the skill. Calling an unfamiliar API, reading its data structure, normalising units and handling missing data is everyday FDE work on the customer side.
Why are pay ranges in the API at all?
Mainly because of the law. According to the law firm Foley & Lardner, Colorado requires every job posting to include pay information, and this covers remote roles if the employer has at least one employee in the state. California requires covered employers to include a pay range in their postings, including postings made by third parties.
New York City also requires postings to state the minimum and maximum annual salary, or hourly wage, for jobs performed at least partly in the city. That is why FDE postings in San Francisco or New York usually carry a pay range, and Greenhouse exposes that data through its API.
Keep the consequence in mind. The data you collect mostly reflects the US market, where the law forces pay disclosure. Do not use it to infer pay in other markets.
What do you need before writing code?
You need Python 3 and the requests library (pip install requests). No API key is required: the Greenhouse documentation states that Job Board data is public, so the GET endpoints need no authentication.
What you do have to find yourself is the board token, the company’s identifier in the API path. The quickest way is to open the company’s careers page. If Greenhouse hosts it, the company identifier usually appears in the URL. Treat this as a practical shortcut, then confirm it with step 1 below.
Step 1: call the endpoint and inspect the structure before trusting it
The job list endpoint takes the form GET https://boards-api.greenhouse.io/v1/boards/{board_token}/jobs. Add content=true so each posting includes the full description, departments and offices. Add pay_transparency=true to receive the pay_input_ranges array; a Greenhouse support article also confirms that pay data only comes back when this parameter is on.
import requests

BOARD = "company_board_token"
URL = f"https://boards-api.greenhouse.io/v1/boards/{BOARD}/jobs"

resp = requests.get(
    URL,
    params={"content": "true", "pay_transparency": "true"},
    timeout=30,
)
resp.raise_for_status()
data = resp.json()
print(data.keys())
Check: the call raises no HTTP error and prints the top-level keys. The code below assumes the postings sit under the jobs key and that each posting has a title field. This is a simplification, so confirm it against the output you just printed.
Step 2: filter for FDE postings
Not every company uses exactly the same job title. The simple approach is to filter on a string in the title, then read through the list yourself.
jobs = data.get("jobs", [])
fde_jobs = [
    j for j in jobs
    if "forward deployed" in (j.get("title") or "").lower()
]
print(len(jobs), len(fde_jobs))
for j in fde_jobs:
    print(j.get("title"))
Check: print every filtered title. If you see titles that don’t belong, or you know the company calls the role something else, adjust the filter now rather than after the table has produced numbers.
Step 3: convert cents to currency and keep postings with no pay range
This step decides whether the table is right. The sample JSON in the Greenhouse documentation shows that each pay range has min_cents, max_cents and currency_type, so you must divide by 100. The code uses .get() so that a range missing a field does not stop the script halfway, in keeping with the rule of never trusting a data structure blindly.
def cents(value):
    return value / 100 if value is not None else None

def to_rows(job):
    ranges = job.get("pay_input_ranges") or []
    if not ranges:
        return [{"title": job.get("title"), "min": None,
                 "max": None, "currency": None}]
    return [{
        "title": job.get("title"),
        "min": cents(r.get("min_cents")),
        "max": cents(r.get("max_cents")),
        "currency": r.get("currency_type"),
    } for r in ranges]

rows = [row for j in fde_jobs for row in to_rows(j)]
Test it with the numbers from the documentation: 5000000 divided by 100 gives 50,000.00, and 7500000 divided by 100 gives 75,000.00 USD. If your table shows a seven-figure number for an engineering role, you almost certainly forgot the division.
Why keep the postings that list no pay? Because there are more of them than you would expect. According to figures from 8 September 2026 compiled by Valletta Software, Palantir’s Forward Deployed Software Engineer pay range appears on only 21 of 52 US postings. Drop the other 31 and you no longer know how much of the market your table represents.
Step 4: write the CSV and count postings with pay
A posting can carry several pay ranges, so the number of rows in the CSV is not the number of postings. The coverage count must therefore run per posting, so your figure can be compared with something like “21 of 52 postings”.
import csv
from datetime import date

with open(f"fde_pay_{BOARD}_{date.today()}.csv", "w", newline="") as f:
    w = csv.DictWriter(f, fieldnames=["title", "min", "max", "currency"])
    w.writeheader()
    w.writerows(rows)

covered = sum(1 for j in fde_jobs if j.get("pay_input_ranges"))
print(f"{covered}/{len(fde_jobs)} postings with a pay range")
Check: open the file and read a few rows, then compare the posting count printed here with the result from step 2. The file name includes the date the data was pulled, because pay ranges change and your table is only accurate as of the moment you ran it.
How do you know your table is right?
Compare it with published pay ranges. Again according to Valletta Software’s figures from 8 September 2026, here are three benchmarks:
| Company | Base pay range | What to note when comparing |
|---|---|---|
| Anthropic | $280,000 to $320,000 | Postings in New York, San Francisco, Seattle |
| OpenAI | $185,000 to $300,000 | Equity on top of the range |
| Palantir | $125,000 to $200,000 | Equity and bonus outside the range |
If your table is far off these benchmarks, suspect your filter or your division before you suspect the market. The last column is also a reminder of something often forgotten: these are base salaries, not total compensation. Comparing Palantir’s midpoint (162,500) with OpenAI’s (242,500) without mentioning equity is a flawed comparison.
The most common mistakes
The most common mistake is forgetting pay_transparency=true and concluding that the company does not publish pay. Next come forgetting to divide by 100, averaging different currencies in a single column, and treating a posting with no pay range as paying zero.
A subtler mistake is calling the API repeatedly in a loop with no stopping point. An API that needs no key is not an invitation to call it freely; for a salary table, running once a day is enough.
How does this skill show up at a customer?
Picture your first week at a logistics customer: you need to pull order data from a system you have never seen. The sequence is almost identical. Make one request, print the structure, confirm the units (cents or dollars, seconds or milliseconds), then count how many records are missing key fields before building any dashboard.
So once the table is done, don’t keep it to yourself. Put it on GitHub with a README stating the date of the data, the share of postings with pay, and the table’s limits.
On a CV, a line such as “built a pipeline to collect public pay ranges, normalise units and report the share of postings missing pay data” shows FDE recruiters exactly what they want to see: you can work with real, messy data and say clearly how far it can be trusted.
The salary table will be out of date in a few weeks. The habit of printing the structure first and then counting the gaps works at every customer.
Was this article useful?
Thanks for the feedback!
4 sources
- Greenhouse Job Board API documentation
- Greenhouse Support: Permissions: Job Admin and above who can create, edit, and delete job posts (pay transparency section)
- Navigate New State Pay Transparency Laws (Foley & Lardner) · 2023-01
- Forward Deployed Engineer Salary in 2026 (Valletta Software) · 2026-09-08