jq: filter and reshape a client's API JSON in the terminal
When a client asks "how many failed orders over 500?", the fastest answer can be a single command, with no notebook in sight.

In brief
- jq is a single executable written in C with no runtime dependencies, so it can be installed straight onto a client's machine.
- Everything in jq is a filter; select keeps the records that match a condition, and @csv writes them out for a spreadsheet.
- Pass values in from the shell with --arg or --argjson instead of stitching quoted strings together yourself.
Half an hour into a client meeting, the operations team asks an ordinary question: how many failed payments over 500 were there this week, and which customers did they belong to?
The data is already in their API, which returns a JSON blob several thousand lines long. You could open a notebook and write a script, or you could type one command and send a CSV before the meeting ends.
That command is usually jq. The official site, jqlang.org, calls it a “lightweight and flexible” command-line JSON processor and compares it to sed, but for JSON. For an FDE, who reads unfamiliar payloads from client systems every day, jq is one of the tools most worth learning early.
Why it suits a client’s machine
A client’s machine rarely has the environment you want.
It may be a locked-down bastion host where you cannot install Python packages and have no root access. jq is written in portable C and depends on no runtime, so all you need is a single executable. It is released under the MIT licence, which helps when you have to ask permission to install tools on someone else’s infrastructure.
Everything is a filter
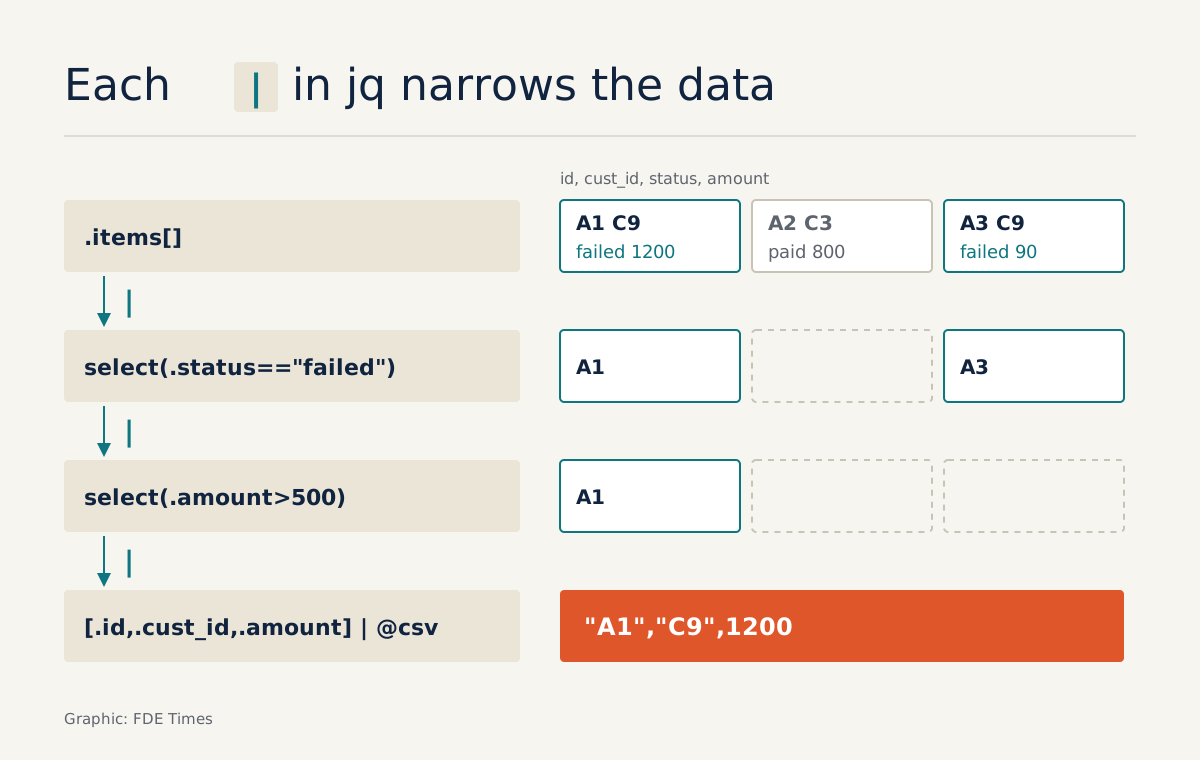
To use jq fluently you need to grasp one idea. The jq 1.8 manual defines it this way: a jq program is a “filter” that takes an input and produces an output. You chain filters with |, just like a shell pipe, and data flows from left to right.
Imagine the client’s API returns a file, orders.json, like this:
{"items": [
  {"id": "A1", "status": "failed", "amount": 1200, "cust_id": "C9"},
  {"id": "A2", "status": "paid",   "amount": 800,  "cust_id": "C3"},
  {"id": "A3", "status": "failed", "amount": 90,   "cust_id": "C9"}
]}
The first step is to split the array into individual records, then keep only the failed orders. The select(f) function does exactly that: it returns its input unchanged if f is true and drops it if not.
jq '.items[] | select(.status == "failed")' orders.jsonThe result is two orders, A1 and A3. Read it left to right: go into the items array, iterate over each element, keep those whose status is failed.
Passing a threshold in from the shell without breaking quotes
Today’s threshold of 500 may be 1000 tomorrow, so do not hard-code it. The clumsy approach is to splice a shell string into the middle of the jq program and then wrestle with single and double quotes. The manual points to a cleaner way: --arg and --argjson pass values into the program as predefined variables.
jq --argjson min 500 \
  '.items[] | select(.status == "failed" and .amount > $min)' orders.json
Now only A1 remains. With three sample records you can count by eye; with several thousand real ones, the next step gives you both the count and the list.
From JSON to a file the client can open
The client’s operations team does not read JSON; they open spreadsheets. The @csv format takes an array and outputs one CSV line, with strings wrapped in double quotes and any quotes inside them doubled. So your job is to build an array of exactly the columns you want, then pass it through @csv.
jq -r --argjson min 500 \
  '.items[] | select(.status == "failed" and .amount > $min)
   | [.id, .cust_id, .amount] | @csv' orders.json > failed.csv
The file failed.csv has a single line: "A1","C9",1200. One line means one order, and the second column says which customer it was. Both halves of the question now have an answer attached.
Sometimes the problem is field names: the client calls it cust_id, your system calls it customer_id. The pair to_entries and with_entries convert between an object and an array of key–value pairs, so you can rename a key without listing every field again:
jq '.items[] | with_entries(.key |= if . == "cust_id" then "customer_id" else . end)' orders.jsonThree mistakes beginners make
The first is confusing --arg with --argjson. --arg passes in a string, while --argjson passes a JSON-encoded value, so 500 stays a number. Compare .amount with the string "500" and you will not get the result you want, and this kind of bug is very hard to spot mid-demo.
The second is feeding a whole object to @csv. The manual states that the input to @csv must be an array, so {"id": "A1", ...} has to become [.id, .cust_id, .amount] first, and that step is what fixes the column order in the spreadsheet.
The third is expecting select to change the data. It only keeps or drops; records that pass through are untouched. To change their shape, add another filter after a |.
The limit: it is a language, not a shortcut
Wikipedia describes jq as both a command-line utility and a domain-specific functional programming language. That gives it a lot of expressive power, but a long jq program is as hard to read as code in any language.
Once a command runs to ten lines with nested conditions, a colleague who inherits the project will find it harder to maintain than a tested Python script.
The practical rule is to use jq for exploration and for answering questions on the spot: inspecting payloads, filtering, exporting files. When the logic becomes a recurring step in the client’s pipeline, move it into code that is tested and reviewed.
What to learn first, and how to show it on a CV
A sensible order is: field access and array iteration, chaining with |, then select, --argjson, @csv, and finally with_entries. The best exercise is to repeat the exact sequence above on an API response from a project you are working on: filter the failed records, pass the threshold in with --argjson, export a CSV, then rename a field.
Do not just list “jq” among your skills. A runbook in a portfolio repo, with a few jq data-checking commands and a short note on what question each one answers, shows a recruiter that you can read and debug data that is not your own.
The CSV export command above is a good starting point: a real question, real data, a real number.
Was this article useful?
Thanks for the feedback!